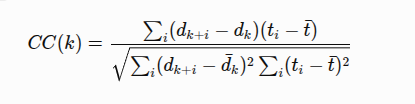import pandas as pd

df = pd.DataFrame(
    {
        "name": ["A", "B", "C", "D"],
        "score": [80, 90, 70, 95]
    },
    index=[10, 20, 30, 40]
)

print(df)

>>>
   name  score
10    A     80
20    B     90
30    C     70
40    D     95

df.loc[20]

>>>
name      B
score    90

# index label 이 20인 행을 찾음.

df.loc[20:30]

>>>
   name  score
20    B     90
30    C     70
# .loc의 slicing의 경우 양 끝값 포함

df.loc[20, "score"]

>>>
90

# index가 20인 행이거니 column이 socre인 열 출력
pandas.DataFrame.iloc
iloc 의 경우 실제 위치를 찾는다.
import pandas as pd

df = pd.DataFrame(
    {
        "name": ["A", "B", "C", "D"],
        "score": [80, 90, 70, 95]
    },
    index=[10, 20, 30, 40]
)

print(df)

>>>
   name  score
10    A     80
20    B     90
30    C     70
40    D     95

df.iloc[1] # 두번쨰 행
>>>
name      B
score    90

# 여기서 1은 index label이 아니라 0부터 세었을때 1번 위치 즉 2번째 행

df.iloc[1, 1] #두번째 행, 두번째 열
>>>
90

#########################################################
           column position
              0       1
           name    score
position 0   A       80      <- index label 10
position 1   B       90      <- index label 20
position 2   C       70      <- index label 30
position 3   D       95      <- index label 40
##########################################################
따라서 아래와 같은경우 loc 과 iloc이 같은 값 반환
df.loc[20, "score"]
>>> 90
df.iloc[1, 1]
>>> 90
loc과는 다르게 iloc의 경우 python의 일반적인 slicing 규칙을 따름.
df.iloc[1:3]
>>>
   name  score
20    B     90
30    C     70
Boolean 을 이용한 loc
import pandas as pd

df = pd.DataFrame(
    {
        "name": ["A", "B", "C", "D"],
        "score": [80, 90, 70, 95]
    },
    index=[10, 20, 30, 40]
)

print(df)

>>>
   name  score
10    A     80
20    B     90
30    C     70
40    D     95

# 먼저
df["score"] > 80
>>>
10    False
20     True
30    False
40     True
Name: score, dtype: bool

df.loc[df["score"] > 80]
>>>
   name  score
20    B     90
40    D     95
correlate(a,b, shift) ---- 두 비슷한 길이의 신호사이의 상대 shift 찾기 (b가 a에 비해 몇 sample 이동했나?)
correlate_template(data, template) ---- 긴 data안에서 짧은 template이 어디에 있는지 찾기 (이 template이 data에 어디에 있나?)
correlate_template은 shift를 지정하지 않고, template이 data의 전체위에서 움직인다.
data
------------------------------------------------------------

template
██████

가능한 위치:

██████
  ██████
    ██████
      ██████
         ...
                              ██████
def _window_sum(data, window_len):
    """Rolling sum of data."""
    window_sum = np.cumsum(data)
    # in-place equivalent of
    # window_sum = window_sum[window_len:] - window_sum[:-window_len]
    # return window_sum
    np.subtract(window_sum[window_len:], window_sum[:-window_len],
                out=window_sum[:-window_len])
    return window_sum[:-window_len]

def correlate_template(data, template, mode='valid', normalize='full',
                       demean=True, method='auto'):
    # if we get Trace objects, use their data arrays
    if isinstance(data, Trace):
        data = data.data
    if isinstance(template, Trace):
        template = template.data
    data = np.asarray(data)
    template = np.asarray(template)
    lent = len(template)
    if len(data) < lent:
        raise ValueError('Data must not be shorter than template.')
    if demean:
        template = template - np.mean(template)
        if normalize != 'full':
            data = data - np.mean(data)


    cc = scipy.signal.correlate(data, template, mode=mode, method=method)
    if normalize is not None:
        tnorm = np.sum(template ** 2)
        if normalize == 'naive':
            norm = (tnorm * np.sum(data ** 2)) ** 0.5
            if norm <= np.finfo(float).eps:
                cc[:] = 0
            elif cc.dtype == float:
                cc /= norm
            else:
                cc = cc / norm
        elif normalize == 'full':
            pad = len(cc) - len(data) + lent
            if mode == 'same':
                pad1, pad2 = (pad + 2) // 2, (pad - 1) // 2
            else:
                pad1, pad2 = (pad + 1) // 2, pad // 2
            data = _pad_zeros(data, pad1, pad2)
            # in-place equivalent of
            # if demean:
            #     norm = ((_window_sum(data ** 2, lent) -
            #              _window_sum(data, lent) ** 2 / lent) * tnorm) ** 0.5
            # else:
            #      norm = (_window_sum(data ** 2, lent) * tnorm) ** 0.5
            # cc = cc / norm
            if demean:
                norm = _window_sum(data, lent) ** 2
                if norm.dtype == float:
                    norm /= lent
                else:
                    norm = norm / lent
                np.subtract(_window_sum(data ** 2, lent), norm, out=norm)
            else:
                norm = _window_sum(data ** 2, lent)
            norm *= tnorm
            if norm.dtype == float:
                np.sqrt(norm, out=norm)
            else:
                norm = np.sqrt(norm)
            mask = norm <= np.finfo(float).eps
            if cc.dtype == float:
                cc[~mask] /= norm[~mask]
            else:
                cc = cc / norm
            cc[mask] = 0
        else:
            msg = "normalize has to be one of (None, 'naive', 'full')"
            raise ValueError(msg)
    return cc
따라서 mode='valid' 인것이 합리적이고 당연하고 실제로 default 값이다. 당연히 template의 길이가 data 보다 짧아야한다.
예를 들어서.
data length     = 1000
template length = 100

#mode='valid'의 결과 길이는 1000-1000+1 = 901

cc[0]은 template와 data[0:100]의 비교 결과
cc[1]은 template와 data[1:101]의 비교 결과
cc[450]은 template와 data[450:550]의 비교결과
Normalization (full)
각 template 위치마다 data window의 normalization을 새로 계산
그래서 full normalization은 위치마다 denominator가 다르다. 따라서 진폭이 달라도 shape가 같으면 cc=1이 될 수 있다.
    """
    Cross-correlation of two signals up to a specified maximal shift.

    This function only allows 'naive' normalization with the overall
    standard deviations. This is a reasonable approximation for signals of
    similar length and a relatively small shift parameter
    (e.g. noise cross-correlation).
    If you are interested in the full cross-correlation function better use
    :func:`~obspy.signal.cross_correlation.correlate_template` which also
    provides correct normalization.

    :type a: :class:`~numpy.ndarray`, :class:`~obspy.core.trace.Trace`
    :param a: first signal
    :type b: :class:`~numpy.ndarray`, :class:`~obspy.core.trace.Trace`
    :param b: second signal to correlate with first signal
    :param int shift: Number of samples to shift for cross correlation.
        The cross-correlation will consist of ``2*shift+1`` or
        ``2*shift`` samples. The sample with zero shift will be in the middle.
    :param bool demean: Demean data beforehand.
    :param normalize: Method for normalization of cross-correlation.
        One of ``'naive'`` or ``None``
        (``True`` and ``False`` are supported for backwards compatibility).
        ``'naive'`` normalizes by the overall standard deviation.
        ``None`` does not normalize.
    :param str method: Method to use to calculate the correlation.
         ``'direct'``: The correlation is determined directly from sums,
         the definition of correlation.
         ``'fft'`` The Fast Fourier Transform is used to perform the
         correlation more quickly.
         ``'auto'`` Automatically chooses direct or Fourier method based on an
         estimate of which is faster. (Only availlable for SciPy versions >=
         0.19. For older Scipy version method defaults to ``'fft'``.)

    :return: cross-correlation function.

    To calculate shift and value of the maximum of the returned
    cross-correlation function use
    :func:`~obspy.signal.cross_correlation.xcorr_max`.

    .. note::

        For most input parameters cross-correlation using the FFT is much
        faster.
        Only for small values of ``shift`` (approximately less than 100)
        direct time domain cross-correlation migth save some time.

    .. note::

        If the signals have different length, they will be aligned around
        their middle. The sample with zero shift in the cross-correlation
        function corresponds to this correlation:

        ::

            --aaaa--
            bbbbbbbb

        For odd ``len(a)-len(b)`` the cross-correlation function will
        consist of only ``2*shift`` samples because a shift of 0
        corresponds to the middle between two samples.
    """
###helper

def _pad_zeros(a, num, num2=None):
    """Pad num zeros at both sides of array a"""
    if num2 is None:
        num2 = num
    hstack = [np.zeros(num, dtype=a.dtype), a, np.zeros(num2, dtype=a.dtype)]
    return np.hstack(hstack)

##################################################################################

def _xcorr_padzeros(a, b, shift, method):
    """
    Cross-correlation using SciPy with mode='valid' and precedent zero padding.
    """
    if shift is None:
        shift = (len(a) + len(b) - 1) // 2
    dif = len(a) - len(b) - 2 * shift
    if dif > 0:
        b = _pad_zeros(b, dif // 2)
    else:
        a = _pad_zeros(a, -dif // 2)
    return scipy.signal.correlate(a, b, mode='valid', method=method)

##################################################################################

def _xcorr_slice(a, b, shift, method):
    """
    Cross-correlation using SciPy with mode='full' and subsequent slicing.
    """
    mid = (len(a) + len(b) - 1) // 2
    if shift is None:
        shift = mid
    if shift > mid:
        # Such a large shift is not possible without zero padding
        return _xcorr_padzeros(a, b, shift, method)
    cc = scipy.signal.correlate(a, b, mode='full', method=method)
    return cc[mid - shift:mid + shift + len(cc) % 2]

##################################################################################
##################################################################################

### main

def correlate(a, b, shift, demean=True, normalize='naive', method='auto'):

    if normalize is False:
        normalize = None
    if normalize is True:
        normalize = 'naive'
    # if we get Trace objects, use their data arrays
    if isinstance(a, Trace):
        a = a.data
    if isinstance(b, Trace):
        b = b.data
    a = np.asarray(a)
    b = np.asarray(b)
    if demean:
        a = a - np.mean(a)
        b = b - np.mean(b)

    # choose the usually faster xcorr function for each method

    _xcorr = _xcorr_padzeros if method == 'direct' else _xcorr_slice
    cc = _xcorr(a, b, shift, method)

    if normalize == 'naive':
        norm = (np.sum(a ** 2) * np.sum(b ** 2)) ** 0.5
        if norm <= np.finfo(float).eps:
            # norm is zero
            # => cross-correlation function will have only zeros
            cc[:] = 0
        elif cc.dtype == float:
            cc /= norm
        else:
            cc = cc / norm
    elif normalize is not None:
        raise ValueError("normalize has to be one of (None, 'naive'))")
    return cc
mode='full' correlation의 중앙 부분만 잘라서 반환 이때 output의 길이는 in1이랑 같게
len(output) = len(in1)
len(master), len(slave)
>>> 1000,1000

##full

signal.correlate(master, slave, mode='full')

lag
-999 ---------------- 0 ---------------- +999

       가능한 모든 shift를 계산


##same

signal.correlate(master, slave, mode='same')

FULL

-999 ---------------- 0 ---------------- +999
          |<------ SAME ------>|
mode = 'valid'
한 신호가 다른 신호 안에 완전히 들어와 있을 때만 correlation을 계산
출력길이는 N-M+1
template matching에 유용함
template이 trace 밖으로 삐져나가는 위치는 아예 계산하지 않으므로
"template 전체가 trace에 존재하는 위치에서만 비교하겠다"
그림으로 비교하면
len(in1)
>>> 5
len(in2)
>>> 3


##full
       x x x x x
y y y
  y y y
    y y y
      y y y
        y y y
          y y y
            y y y

총 7 positions

##same
       x x x x x
    y y y
      y y y
        y y y
          y y y
            y y y

총 5 positions


##valid
       x x x x x

       y y y
         y y y
           y y y

총 3 positions
method
direct
time domain에서 직접 수행(시그마 직접 계산)
C[k]=n∑x[n]y[n−k]
fft
freq. domain에서 두 spectrum을 곱하고 다시 IFFT
auto
scipy가 직접 판단 (신호길이에 따라 direct와 auto의 계산 효율 차이가 많이 나기 때문)
IFTYPE = file type LEVEN = evenly sampled time series DELTA = spacing in time of data points IDEP = physical unit of the data
DEPMIN = minimum amplitude DEPMAX = maximum amplitude DEPMEN = mean amplitude
OMARKER = event origin marker AMARKER = first arrival (P) marker T0MARKER = t0 (S) marker
KZDATE = reference date KZTIME = reference time IZTYPE = type of reference time
KSTNM = station name CMPAZ = component azimuth relative to north CMPINC = component "incidence angle" reletive to the vertical STLA = station latitude STLO = station longitude STEL = station elevation STDP = station depth below surface (meters)
DIST = source receiver distance in km AZ = azimuth BAZ = back azimuth GCARC = great circle distance
LOVROK = TRUE if it is okay to overwrite this file on disk NVHDR = Header version number. Current value is the integer 6. SCALE = Multiplying scale factor for dependent variable NORID = Origin ID (CSS 3.0) NEVID = Event ID (CSS 3.0) NWFID = Waveform ID (CSS 3.0) LPSPOL = TRUE if station components have a positive polarity (left-hand rule) LCALDA = TRUE if DIST, AZ, BAZ, and GCARC are to be calculated from station and event coordinates KCMPNM = Component name KNETWK = Network name MAG = Event magnitude